What Is an Abliterated LLM? How Abliteration Changes AI Refusal Behavior
An emerging technique in open-weight artificial intelligence called abliteration lets researchers modify how a large language model responds to requests it would normally refuse. Rather than retraining a model from scratch, the technique edits parts of its internal computation or weights to weaken a learned refusal behavior.
The result is commonly called an abliterated LLM: a model whose tendency to produce refusal responses has been deliberately reduced. The term is technical, but the implications are practical. It touches model interpretability, open-source experimentation, AI safety, and the responsibilities of anyone deploying modified models.
Importantly, abliteration does not make a model more knowledgeable, more intelligent, or automatically more accurate. It changes a behavior associated with refusal. Understanding that distinction is essential before treating an abliterated model as a useful development tool—or a production-ready system.
What does “abliterated LLM” mean?
An abliterated LLM is generally an open-weight language model that has been altered to reduce a refusal-related signal in its internal representations. The word “abliteration” blends ablation (removing or suppressing a component) with obliteration. It describes a family of model-editing approaches rather than a new model architecture or an official model category.
Most conversational models are trained to follow useful instructions while declining certain harmful or inappropriate requests. Those behaviors emerge from several stages of training and from the model's learned internal representations. Abliteration targets a refusal-associated component of that behavior. The model's weights and architecture may remain the same size, but its response tendencies can change.
It is useful to distinguish three ideas:
- Prompt jailbreak: The model's weights stay unchanged; a specially constructed prompt attempts to make it ignore its usual behavior.
- Fine-tuning: Additional training examples or optimization update model parameters to change behavior.
- Abliteration: A direct intervention on internal activations or model weights aims to suppress a refusal-related direction, often without gradient-based retraining.
These methods can produce superficially similar outputs, but they operate in different ways. A model described as “uncensored” is not necessarily abliterated; the label alone does not reveal how it was produced.
The research behind abliteration: the refusal direction
A key foundation came from the 2024 paper “Refusal in Language Models Is Mediated by a Single Direction” by Andy Arditi and colleagues, published in the NeurIPS 2024 proceedings.
The researchers studied 13 open-source chat models, with sizes up to 72 billion parameters. They reported that a particular direction in a model's residual-stream activation space was strongly associated with refusal behavior. Removing that component reduced the models' tendency to refuse harmful instructions; adding it could induce refusals even for harmless prompts.
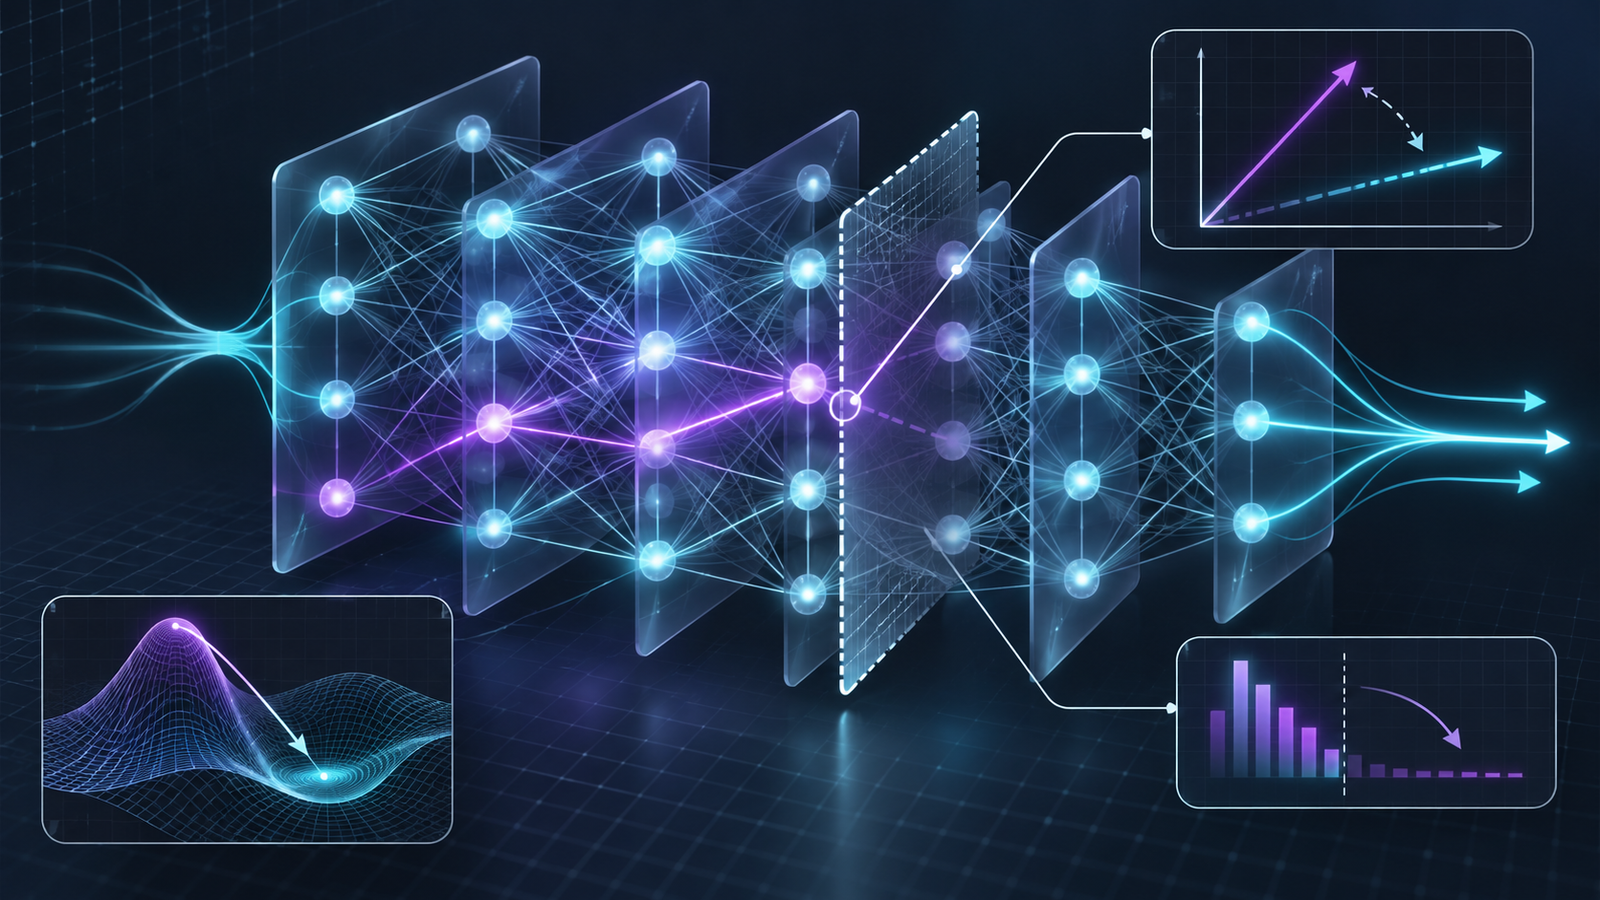
In plain language, imagine the model's internal state as a point in a very high-dimensional space. A direction is a vector through that space. If a component of the state aligns with a refusal-associated direction, it can contribute to the model producing a refusal. An intervention can suppress that component and change the resulting behavior.
This was an important mechanistic-interpretability result because it showed that at least some refusal behavior could be influenced through a relatively compact internal signal. It did not establish that all safety behavior, values, or policy reasoning live in one switch.
How does abliteration work?
Implementations differ, but a common conceptual workflow has four stages:
- Prepare contrasting prompts. Researchers assemble examples that should elicit a refusal and examples that should receive a normal answer. The sets need careful curation: prompt wording, topic, length, and context can all affect the comparison.
- Record internal activations. The model processes the prompts, and the researcher captures selected hidden-state activations at chosen layers and token positions.
- Estimate a refusal-associated direction. A common approach compares average activations across the two prompt groups. The resulting difference vector is normalized and treated as an estimate of a refusal-related direction.
- Apply an intervention and evaluate it. Depending on the method, the direction may be projected out of activations during inference or removed from selected weight matrices so the change persists in the saved model.
The important distinction is between activation steering and weight editing. Steering changes the model's internal state while it is running, typically through a hook or intervention. Weight editing changes stored parameters so the behavior change travels with the modified checkpoint. Both can be discussed under the broad umbrella of abliteration, but they are not operationally identical.
Does abliteration remove all AI safety protections?
No. That is an overstatement. Abliteration can weaken a refusal behavior that is represented in the model's internal computation, but it does not automatically remove every safety-related capability or control.
A deployed AI system may have multiple layers of protection: model training, system instructions, input and output moderation, tool permissions, application-level authorization, rate limits, logging, and human review. Editing a model checkpoint does not, by itself, disable controls implemented outside that checkpoint.
It is equally important not to assume that all refusals are identical. A model may decline because a request is harmful, because it lacks necessary information, because the request is outside its capabilities, or because the prompt is ambiguous. Reducing refusal behavior indiscriminately can affect appropriate caution as well as unnecessary over-refusal.
What newer research says about the “single direction” explanation
The original single-direction result is influential, but it should not be treated as a universal description of every kind of refusal in every model. A 2026 study, “There Is More to Refusal in Large Language Models than a Single Direction”, examined 11 categories of refusal and non-compliance in Gemma and Llama instruction-tuned models.
That work reported that different refusal categories can correspond to geometrically distinct directions, even though linear steering along those directions can produce similar changes in refusal rates. Its ablation experiments also found that results differed between the tested model families. In some settings, refusal behavior remained after an intervention.
The practical lesson is that refusal is not necessarily one universal switch. The original finding demonstrates a useful and measurable mechanism in the models studied; later work highlights the diversity and redundancy that can exist across refusal types and architectures. Any claim about a particular abliterated checkpoint therefore needs direct evaluation.
Why are developers experimenting with abliterated models?
Research into model internals
Abliteration offers a way to test hypotheses about how learned behaviors are represented. Researchers can compare a model before and after an intervention, inspect which behaviors change, and learn where a simple linear explanation breaks down.
Studying over-refusal
Some models refuse benign requests because a topic resembles a risky one or because the request is poorly specified. Controlled experiments with refusal-related interventions can help researchers understand the boundary between appropriate caution and unnecessary refusal. The goal of such research should be measured behavior, not simply the lowest possible refusal rate.
Open-weight model customization
Developers working with open-weight models may explore model edits as part of controlled experimentation. But a lower refusal rate is not proof of better utility. A modified model may become less reliable, more likely to produce unsafe material, or worse at tasks that depend on calibrated uncertainty.
Risks and limitations developers should understand
- Safety behavior can weaken: A model may become more willing to comply with requests that should be declined. This raises the burden on the application that hosts it.
- Capability regressions are possible: An intervention can affect more than the target behavior. Reasoning, instruction following, factual accuracy, or style may change.
- Results are model-specific: A method that works on one architecture or checkpoint may not transfer cleanly to another.
- Refusal metrics can mislead: A lower refusal rate may look like progress even if harmful compliance rises or benign-task accuracy falls.
- Model provenance matters: A downloaded checkpoint may have been edited, quantized, merged, or otherwise changed. Its name is not a substitute for a trustworthy model card and reproducible evaluation.
How should teams evaluate an abliterated LLM?
Teams should compare the modified checkpoint with its original version using the same prompts, decoding settings, context, and evaluation environment. A useful test plan should include at least four dimensions:
- Benign task performance: Test ordinary writing, coding, summarization, reasoning, and domain-specific tasks that the model is expected to support.
- Appropriate refusal: Measure whether the model still declines clearly harmful requests and handles sensitive situations responsibly.
- Over-refusal and ambiguity: Test harmless requests that resemble risky topics, plus incomplete prompts where asking a clarifying question is better than guessing.
- Application-level controls: Verify that moderation, access control, tool authorization, audit logs, and human approval continue to work independently of model behavior.
Record both successes and failures. Keep a baseline, version the checkpoint, document the editing method, and repeat evaluations after changes to the model, prompt template, or surrounding application. For systems that can use tools or access sensitive data, model evaluation should sit inside a broader security design. Our guides on AI agent identity and permissions and building trustworthy AI agents explore complementary controls.
Should you use an abliterated LLM in production?
For most production teams, the right starting point is not to remove refusals wholesale. First identify the actual problem: is the model refusing legitimate work, misunderstanding context, or following a policy that is too broad? Prompt design, better retrieval, clearer task boundaries, a different model, or carefully scoped policy changes may address the issue without weakening safety behavior across the board.
If a team does experiment with an abliterated checkpoint, it should treat that checkpoint as a distinct model requiring its own safety and capability evaluation. Keep it isolated from sensitive systems until it passes testing. Apply independent policy enforcement at the application layer, restrict tools and data access by least privilege, and maintain monitoring and rollback options.
The future of abliteration and model interpretability
Abliteration illustrates a broader shift in AI research: developers are moving beyond treating language models as black boxes and investigating how internal representations contribute to observable behavior. That knowledge can support better debugging and more precise interventions, but it also creates new ways to alter safeguards.
The research story is still evolving. The 2024 single-direction result showed that a refusal-related signal could be identified and manipulated in a range of open models. Newer work suggests that refusal categories, styles, and architectures can be more complex than a single-vector account implies. The responsible conclusion is neither that safety is trivial to remove nor that one edit explains every model. It is that internal behavior can be studied and changed—and that every change needs evidence-based evaluation.
Conclusion
An abliterated LLM is an open-weight language model modified to reduce learned refusal behavior, commonly by suppressing a refusal-associated direction in its activations or weights. The technique is valuable for interpretability research and controlled experiments, but it does not create new intelligence, guarantee unchanged capabilities, or remove every safety layer.
For developers, the central question should not be “How do we make the model refuse less?” It should be “Which behavior are we changing, what else changes with it, and what independent controls keep the complete system trustworthy?” That is the difference between an interesting model edit and a responsible AI deployment.
Comments
0To comment, choose whether you want to register or continue as a guest.